What shipped on 22 September
On 22 September 2026 Microsoft added GPT-6 Sol and GPT-6 Luna to generally available Foundry deployments, in GPT-6 Astra, Sol, and Luna for production AI agents. Sol is the cost-efficient high-end row under Astra. Artificial Analysis the same day said the list price is about half of GPT-5.6 Sol: $2 input and $10 output per million tokens, with a 90% cache-read discount and a 25% cache-write premium.
AshnaAI lists the catalog id `gpt-6-sol` on the same Azure Responses path as `gpt-6-astra`. The context window on that row is 1.05 million tokens. Pin it in chat or pass the id through the OpenAI-compatible API.
Benchmarks vs GPT-5.6 Sol and Luna
Read Sol’s column as a cost cut with a small coding gain, not as a new flagship. Coding Agent Index moves from 55 to 57. Terminal-Bench 4.0 in the Codex harness moves from 37% to 43%. SWE-Atlas-QnA moves from 54% to 58%. Hallucination rate on AA-Omniscience falls from 92% to 60%, partly because Sol answers fewer questions (83% attempted versus 99%) and accuracy slips from 59% to 54%. AutomationBench-AA moves from 60% to 62%. Artificial Analysis also says Sol drops about 100 Elo on GDPval-AA v2.1. The Intelligence Index cost per task is $1.06 versus $1.99 for GPT-5.6 Sol.
The table is Artificial Analysis at max effort, dated 22 September 2026. It is an independent scoreboard, not OpenAI’s launch table. GPT-6 Astra still leads OpenAI’s own 3 September computer-use and science cells; those Astra numbers are on the GPT-6 Astra launch post.
| Benchmark | GPT-6 Sol | GPT-5.6 Sol | GPT-6 Luna | GPT-5.6 Luna | |
|---|---|---|---|---|---|
| Coding agents | Coding agents | ||||
| Coding Agent Index (Codex harness) | 57 | 55 | 41 | 43 | |
| Terminal-Bench 4.0 (Codex harness) | 43% | 37% | — | — | |
| SWE-Atlas-QnA | 58% | 54% | 44% | 49% | |
| DeepSWE v1.1 | — | — | 64% | 66% | |
| Knowledge and agents | Knowledge and agents | ||||
| AA-Omniscience Index | 27 | 22 | 1 | −10 | |
| Hallucination rate (lower is better) | 60% | 92% | 77% | 93% | |
| AutomationBench-AA | 62% | 60% | 53% | 50% | |
| Terminal-Bench 4.0 (Intelligence Index breakdown) | 44% | 40% | 13% | 12% | |
What the token bill looks like
Sol at $2 / $10 is the row to pin when GPT-5.6 Sol was the default and the job does not need Astra. Astra remains $10 / $50. Luna is $0.10 / $0.50. Cached input is 10% of the uncached input rate. Cache writes are 1.25× uncached input. On Ashna, reasoning tokens for this family are billed at 1.5× the short-context output rate ($15 per million for Sol).
| Rate per 1M tokens | GPT-6 Sol | GPT-6 Luna | GPT-6 Astra | GPT-5.6 Sol | GPT-5.6 Luna |
|---|---|---|---|---|---|
| Input | $2.00 | $0.10 | $10.00 | $4.00 | $0.20 |
| Cached input | $0.20 | $0.01 | $1.00 | $0.40 | $0.02 |
| Cache write | $2.50 | $0.125 | $12.50 | $5.00 | $0.25 |
| Output | $10.00 | $0.50 | $50.00 | $20.00 | $1.20 |
Long context is a separate Azure rate
Microsoft’s long-context column for Sol is $4 input, $0.40 cached input, $5 cache write, and $15 output. Ashna’s billed sheet stays on the short-context rates. Do not assume a prompt over a few hundred thousand tokens is still $2 / $10 at the provider.
| Rate per 1M tokens | GPT-6 Sol | GPT-6 Luna |
|---|---|---|
| Input | $4.00 | $0.20 |
| Cached input | $0.40 | $0.02 |
| Cache write | $5.00 | $0.25 |
| Output | $15.00 | $0.75 |
When to pin Sol instead of Astra or Luna
Pin GPT-6 Astra when the job is computer use, science, or the cells Astra published on 3 September. Pin GPT-6 Luna or GLM-5.3-Flash when the job is high volume and a two-point coding-index gap is not worth $10 output. Pin Sol for the middle: agent and coding work that used to sit on GPT-5.6 Sol.
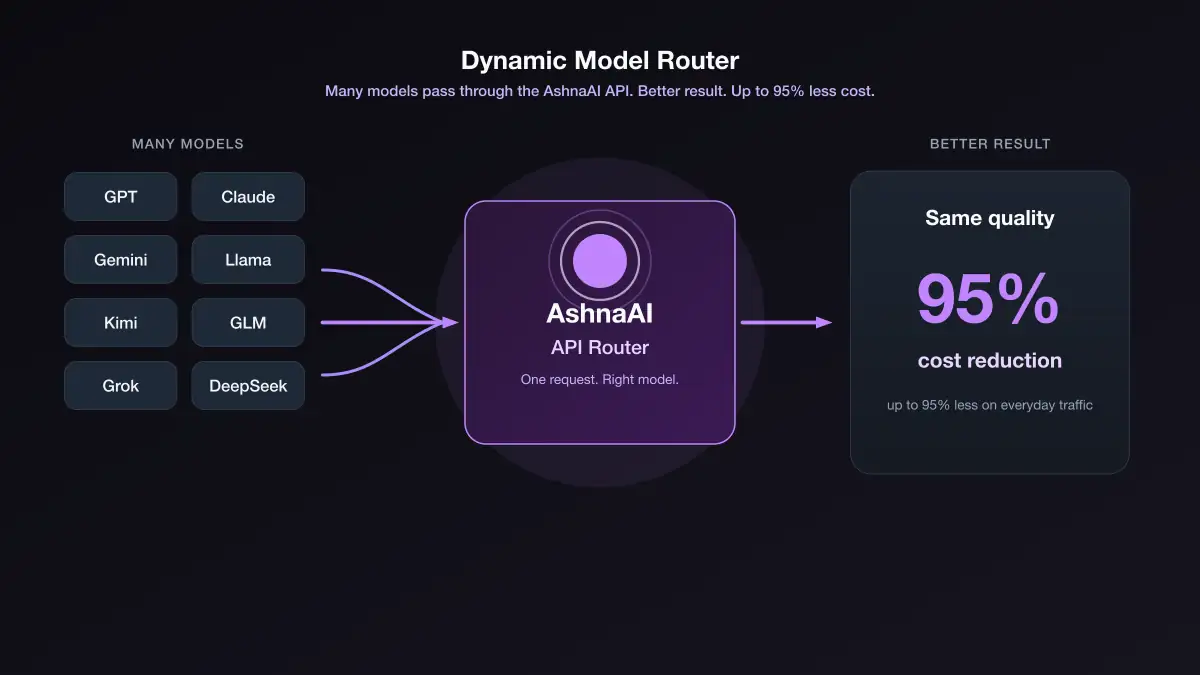
Everyday mixed chat can stay on Ashna-X1, which routes the task instead of locking one id. Cost ladder: Cheapest coding AI vs Claude Opus 5 and GPT-5.6 Sol.
Try gpt-6-sol now
New accounts start at app.ashna.ai/signup. Open GPT-6 Sol in AshnaAI chat. Keep GPT-6 Luna and GPT-6 Astra on the same account so the pin is a switch, not a new vendor.
Product API traffic uses Account → API and the AshnaAI API docs. The model id is `gpt-6-sol`.
Sourced to Microsoft’s Foundry post for GPT-6 Astra, Sol, and Luna, and to Artificial Analysis on 22 September 2026. Benchmark cells are copied from that Artificial Analysis article, including regressions. Prices are Azure Global Standard short context, the sheet Ashna bills. Does not invent scores OpenAI did not publish on these pages.
Topics
Related
- AshnaAI for Work
- AshnaAI vs ChatGPT
- AshnaAI vs Claude
- Large Language Model (LLM)
- Foundation Model
- gpt 6 luna launch benchmarks
- gpt 6 astra launch benchmarks
- deepseek v4 1 flash launch benchmarks
- glm 5 3 flash vs gpt 5 6 sol
- pin glm 5 3 flash for coding
- how to call any catalog model through the api
- cheapest coding ai vs claude opus 5 and gpt 5 6 sol
- how to use ashna x1 instead of picking models yourself
- ashna x1 task aware model routing
Try this in AshnaAI. Create a free account.
Found this article insightful?
Share it with fellow builders, founders, and AI practitioners.